Modern Application Framework: Structure…
Breaking into product management can feel confusing when job descriptions…
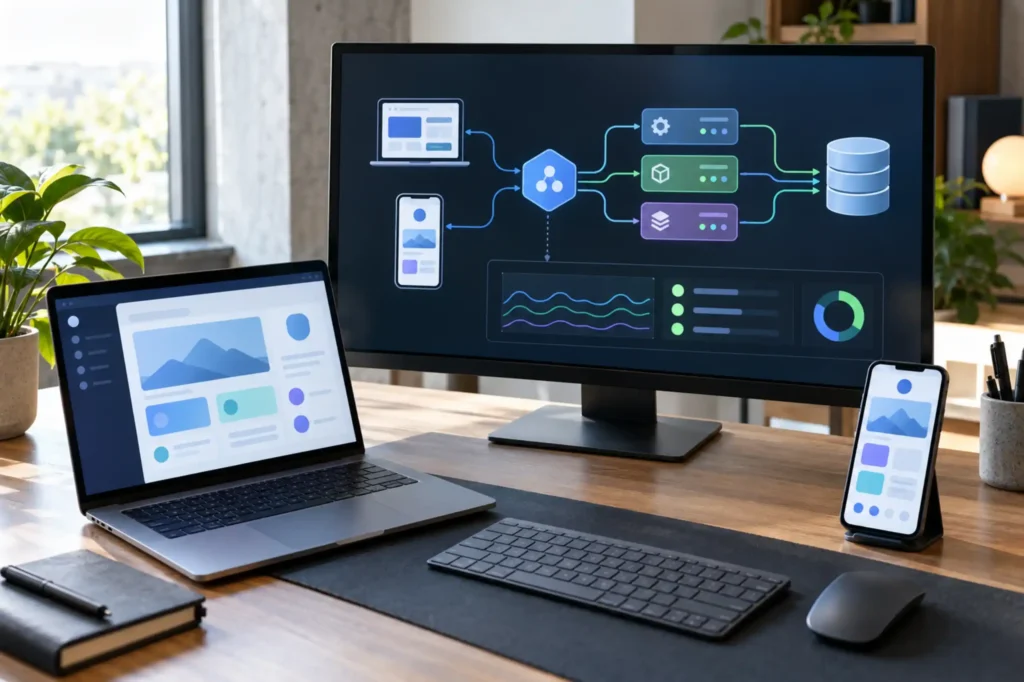
One failed release can interrupt orders, payments, or everyday work. Hidden dependencies make those failures harder to contain and diagnose. In practice, modern application architecture for the enterprise describes how an organization connects its application components, manages data, controls access, and handles failures.
The aim is to support business needs while keeping changes, access, and failures manageable. The important questions are where components should be separated, how data stays correct, and who takes responsibility when something goes wrong.
Separating an application into services helps when the divisions reflect distinct business responsibilities, such as billing and inventory. Splitting code while leaving shared dependencies can give teams more components to operate without making releases any simpler.
A modular monolith keeps clearly separated business functions within one deployable application. This can suit a team that needs manageable code boundaries and has little reason to operate separate services.
Microservices divide capabilities into independently deployable services. They can support separate release schedules and scaling, but each network connection introduces another potential failure point.
Before separating a capability, a useful review asks:
The design should make responsibilities clearer. If a change still requires every team to coordinate, the services may remain too dependent on one another.
When services store their own data, updates may reach different components at different times. The design needs rules for delayed messages, repeated requests, and operations that only partly succeed.
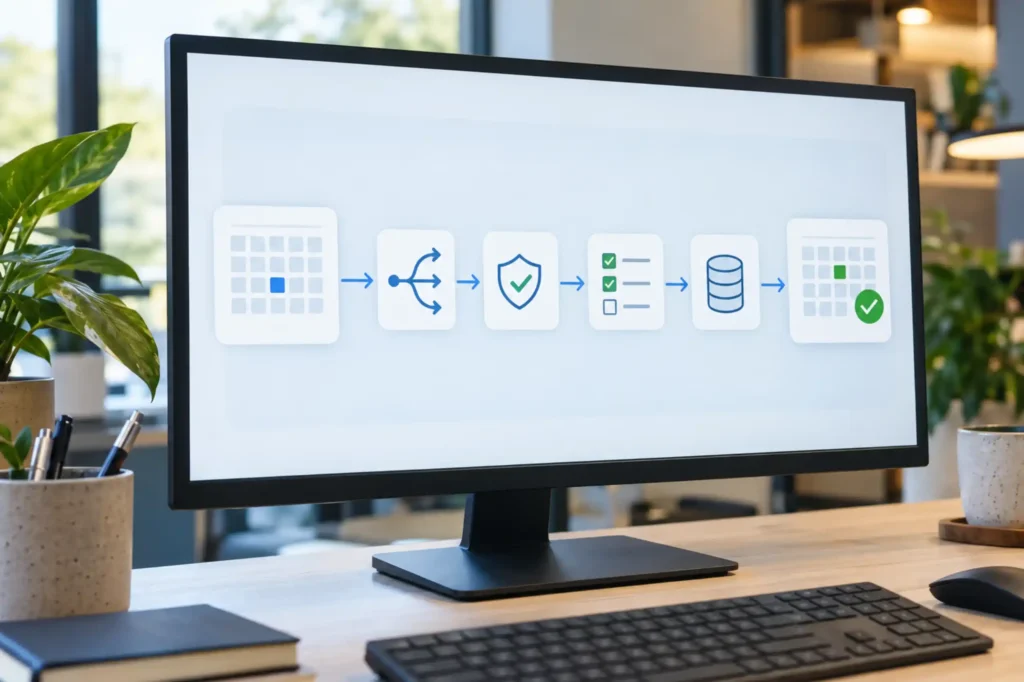
For example, suppose a booking application reserves a room and requests payment. The payment request times out. The booking service now has an uncertain result: the payment might have failed, or the charge might have succeeded before the response was lost.
Repeating the request without duplicate protection could charge the customer twice. A safer approach reuses the same operation identifier on retries so the payment handler can recognize and prevent duplicate processing.
The workflow also needs a way to check unresolved payments and release unpaid reservations. API integration depends on agreed data formats, error responses, and compatibility rules.
A delayed reporting update may be acceptable. Conflicting reservations for the same room require controls that prevent both bookings from being accepted.
Security checks and recovery procedures need to cover the whole workflow. A component can be correctly configured while the connections around it still expose sensitive data or allow an outage to spread.
Authentication verifies identity; authorization controls what that identity can do. Users and services need permissions limited to their responsibilities, with protected credentials and checks on sensitive actions.
Reliability also depends on how components respond to trouble. Timeouts limit waiting, while retries may help with temporary faults. Retries need limits because repeatedly calling an overloaded service can worsen the outage.
Observability is the ability to understand system behavior from operational evidence. Logs describe events, metrics show patterns, and traces follow requests across components. Monitoring should connect these signals to failed bookings or delayed invoices.
Recovery tests need to show that the required data and services can be restored together. Each critical workflow also needs a named owner for incident decisions and recovery checks.
Migration costs include engineering work, running old and new components together, and supporting the result. Hosting charges are only one part.
Continuous delivery keeps software ready for release through automated builds, tests, and repeatable deployment processes. It does not remove the need to check data changes and compatibility.
A practical migration sequence is:
Rollback deserves attention before deployment. Restoring an older application version may fail if the database structure has changed. The plan must cover stored data and component compatibility as well as code.
A migration has a stronger business case when teams can explain the improvement and the ongoing work it creates.
Good decisions about modern application architecture for the enterprise start with business requirements and operating constraints. A design needs to explain how work gets done, how changes are released, and how the organization recovers from failure.
A good design stays understandable and manageable as business requirements change. Extra components need a clear purpose and a team with the time and skills to maintain them.
Use this Ebtechsol guide to review one critical workflow before committing to an architecture change.
No. Enterprise applications can use a modular monolith when that design meets their operational needs. Separate services make sense when independent deployment or scaling solves a concrete problem.
No. Applications can run on premises, in the cloud, or across both. The choice depends on operating requirements, existing dependencies, data constraints, and the team’s ability to maintain the environment.
An API gateway provides a common entry point for selected application interfaces. It can route requests and apply shared controls, such as request limits. Services still need appropriate access checks.
A service publishes an event when something happens, allowing other components to react separately. Consumers need rules for delayed or repeated messages, and the workflow needs visible failure handling.
It can be acceptable when the business tolerates temporary disagreement between records. The system still needs reliable update delivery and ways to handle conflicts or missing messages.
A trace should show the path and timing of a request across participating components. It helps locate slow dependencies and connect a visible failure with the operations behind it.
Services need verifiable identities and permissions limited to their responsibilities. Sharing credentials across components makes accountability harder and can increase the damage if a component is compromised.
Clear interfaces, exportable data, and documented dependencies can reduce switching difficulty. Abstraction adds maintenance work, so portability decisions should reflect realistic future needs rather than hypothetical moves.
A useful review connects design decisions to business risks, dependencies, ownership, and failure scenarios. Diagrams help when they explain real request paths and data responsibilities instead of listing technologies.
Success means the targeted problem improved without unacceptable regressions. Relevant evidence includes workflow correctness, release reliability, incident impact, operating effort, and costs compared with the starting conditions.
Breaking into product management can feel confusing when job descriptions…
Breaking into product management can feel confusing when job descriptions…
Breaking into product management can feel confusing when job descriptions…

EB Technical Solutions FZE /
EB TECHNICAL SOLUTIONS (PVT.) LIMITED
Copyright © 2026 EBTECHSOL

Ask me anything about AI Automation, API Integration, SaaS Development or our Services.
Just get in touch via text or microphone.